Backed by market attractiveness analysis, total addressable market sizing, company benchmarking matrices, interactive Excel dashboards, wider supply chain intelligence, emerging startup coverage, and detailed product-level insights, The Business Research Company’s 2026 market reports are designed to offer research that is more actionable and strategically valuable than ever.
Synthetic Evaluation Data Generation Market Set To Climb From $2.39 Billion In 2026 To $7.09 Billion By 2030
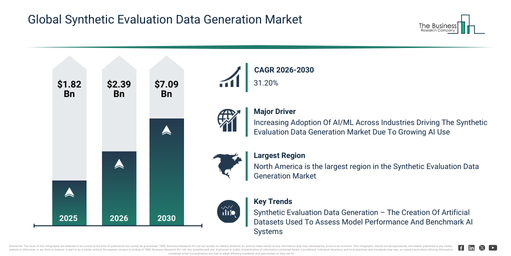
The market for synthetic evaluation data generation has witnessed exponential growth in recent years. The market is anticipated to increase from $1.82 billion in 2025 to $2.39 billion in 2026, achieving a compound annual growth rate (CAGR) of 31.5%. Several factors contributed to this historical expansion, including the escalating demand for secure testing data, the increasing necessity for scalable test datasets, a heightened focus on data privacy preservation, the growing need for diverse evaluation scenarios, and the increased integration of automated testing processes.
The synthetic evaluation data generation market size is expected to undergo significant growth in the coming years. It is projected to reach $7.09 billion by 2030, demonstrating a compound annual growth rate (CAGR) of 31.2%. This growth during the forecast period can be linked to heightened enterprise investment in quality assurance, an increasing need for high-fidelity evaluation datasets, a greater demand for scalable and repeatable testing, the wider implementation of continuous delivery workflows, and an expanding preference for vendor-managed data services. Prominent trends anticipated within this forecast period include advancements in artificial intelligence-driven synthetic data synthesis, new approaches in machine learning-powered pattern and anomaly replication, developments concerning natural language processing-enabled text data synthesis, progress in robotic process automation-assisted test data workflows, and novel approaches in application programming interface-based data provisioning.
Get A Free Sample Report With In-Depth Market Insights:
Synthetic Evaluation Data Generation Market Growth Catalysts And Demand Drivers
The widespread uptake of AI and machine learning (ML) across various sectors is anticipated to fuel expansion in the synthetic evaluation data generation market in the future. These technologies enable computers to learn from data, recognize patterns, and make smart decisions requiring minimal human involvement. The proliferation of AI and machine learning (ML) in different industries is on the rise because these solutions boost operational efficiency, automate routine tasks, and facilitate more intelligent, data-informed choices, thereby enhancing productivity and competitive edge. Synthetic evaluation data generation facilitates this trend by offering artificial evaluation datasets that organizations can utilize to test, validate, and benchmark ML models, especially when real-world data is scarce, costly, or sensitive. As an example, the Office for National Statistics, a US-based government department, reported in March 2025 that AI adoption saw an increase from 9% in 2023 to 22% in 2024. Consequently, the expanding embrace of AI and machine learning (ML) across industries is a key factor propelling the synthetic evaluation data generation market’s growth.
Synthetic Evaluation Data Generation Market Segment Outlook: Which Categories Are Growing Fastest?
The synthetic evaluation data generation market covered in this report is segmented –
1) By Component: Software, Services
2) By Data Type: Text, Image, Audio, Other Data Types
3) By Deployment Mode: Cloud, On-Premises
4) By Application: Model Training, Model Testing and Validation, Data Augmentation, Security And Privacy, Other Applications
5) By End-User: BFSI, Healthcare, Automotive, Retail and E-commerce, IT And Telecommunications, Government, Other End-Users
Subsegments:
1) By Software: Data Generation Platforms, Data Masking Tools, Data Anonymization Tools, Data Augmentation Tools, Synthetic Data Management Tools, AI/ML Model Simulation Tools
2) By Services: Consulting Services, Implementation Services, Support and Maintenance Services, Training and Education Services, Custom Data Solutions Services
Synthetic Evaluation Data Generation Market Trends Shaping Long-Term Demand
Major companies operating in the synthetic evaluation data generation market are primarily focusing on synthetic evaluation data generation, particularly through synthetic data generation pipelines, to facilitate the testing, validation, and comparison of machine-learning model performance under controlled and repeatable conditions. A synthetic data generation pipeline constitutes an automated workflow that references real data to construct realistic, privacy-safe artificial datasets suitable for testing, analytics, and machine learning applications. As an illustration, in June 2024, NVIDIA Corporation, a US-based technology company, launched the Nemotron-4 340B family of open models, which includes base, instruct, and reward variants, serving as an open synthetic data generation pipeline to more effectively train large language models (LLMs), especially in data-scarce domains like healthcare, finance, and manufacturing. The instruct model is responsible for generating diverse, high-quality synthetic data that reflects real-world distributions, thereby enhancing LLM robustness, while the reward model evaluates and filters outputs based on criteria such as helpfulness, correctness, coherence, complexity, and verbosity, achieving top performance on the Hugging Face RewardBench leaderboard.
Synthetic Evaluation Data Generation Market Competitive Landscape: Which Companies Lead The Industry?
Major companies operating in the synthetic evaluation data generation market are Amazon Web Services Inc., Microsoft Corporation, Synthesized Ltd., Snorkel AI Inc., Kognic AB, TonicAI Inc., Parallel Domain Inc., Gretel.ai Inc., Synthesis AI Inc., MDClone Ltd., MOSTLY AI Solutions MP GmbH, Rendered.ai Corporation, Anyverse S.L., YData Technologies S.L., Cognata Ltd., DataCebo Inc., Synthex Labs, OneView AI, DiffuseDrive Inc., syntheracorp
View The Full Synthetic Evaluation Data Generation Market Report:
Synthetic Evaluation Data Generation Market Regional Breakdown: Where Is Demand Concentrated?
North America was the largest region in the synthetic evaluation data generation market in 2025. Asia-Pacific is expected to be the fastest-growing region in the forecast period. The regions covered in the synthetic evaluation data generation market report are Asia-Pacific, South East Asia, Western Europe, Eastern Europe, North America, South America, Middle East, Africa.
Reach Out To Our Team:
The Business Research Company: https://www.thebusinessresearchcompany.com/
Americas: +1 310-496-7795
Asia: +44 7882 955267 & +91 8897263534
Europe: +44 7882 955267
Email us at: marketing@tbrc.info
Follow us on:
LinkedIn: https://in.linkedin.com/company/the-business-research-company
YouTube: https://www.youtube.com/channel/UC24_fI0rV8cR5DxlCpgmyFQ
Global Market Model: https://www.thebusinessresearchcompany.com/global-market-model
Wasay has over a decade of experience in market research, data modelling, and analytics, with prior experience at GlobalData and Decision Tree Consulting Services. At The Business Research Company , he leads research operations across syndicated studies, customized consulting engagements, and the Global Market Model platform. His professional experience includes supporting organizations such as Boston Consulting Group, KPMG, and Ernst & Young. Wasay holds a degree in Electronics and Communications Engineering, postgraduate management qualifications from International Management Institute Belgium and Indian School of Business and Entrepreneurship, and completed the Integrated Program in Business Analytics from Indian Institute of Management Indore.